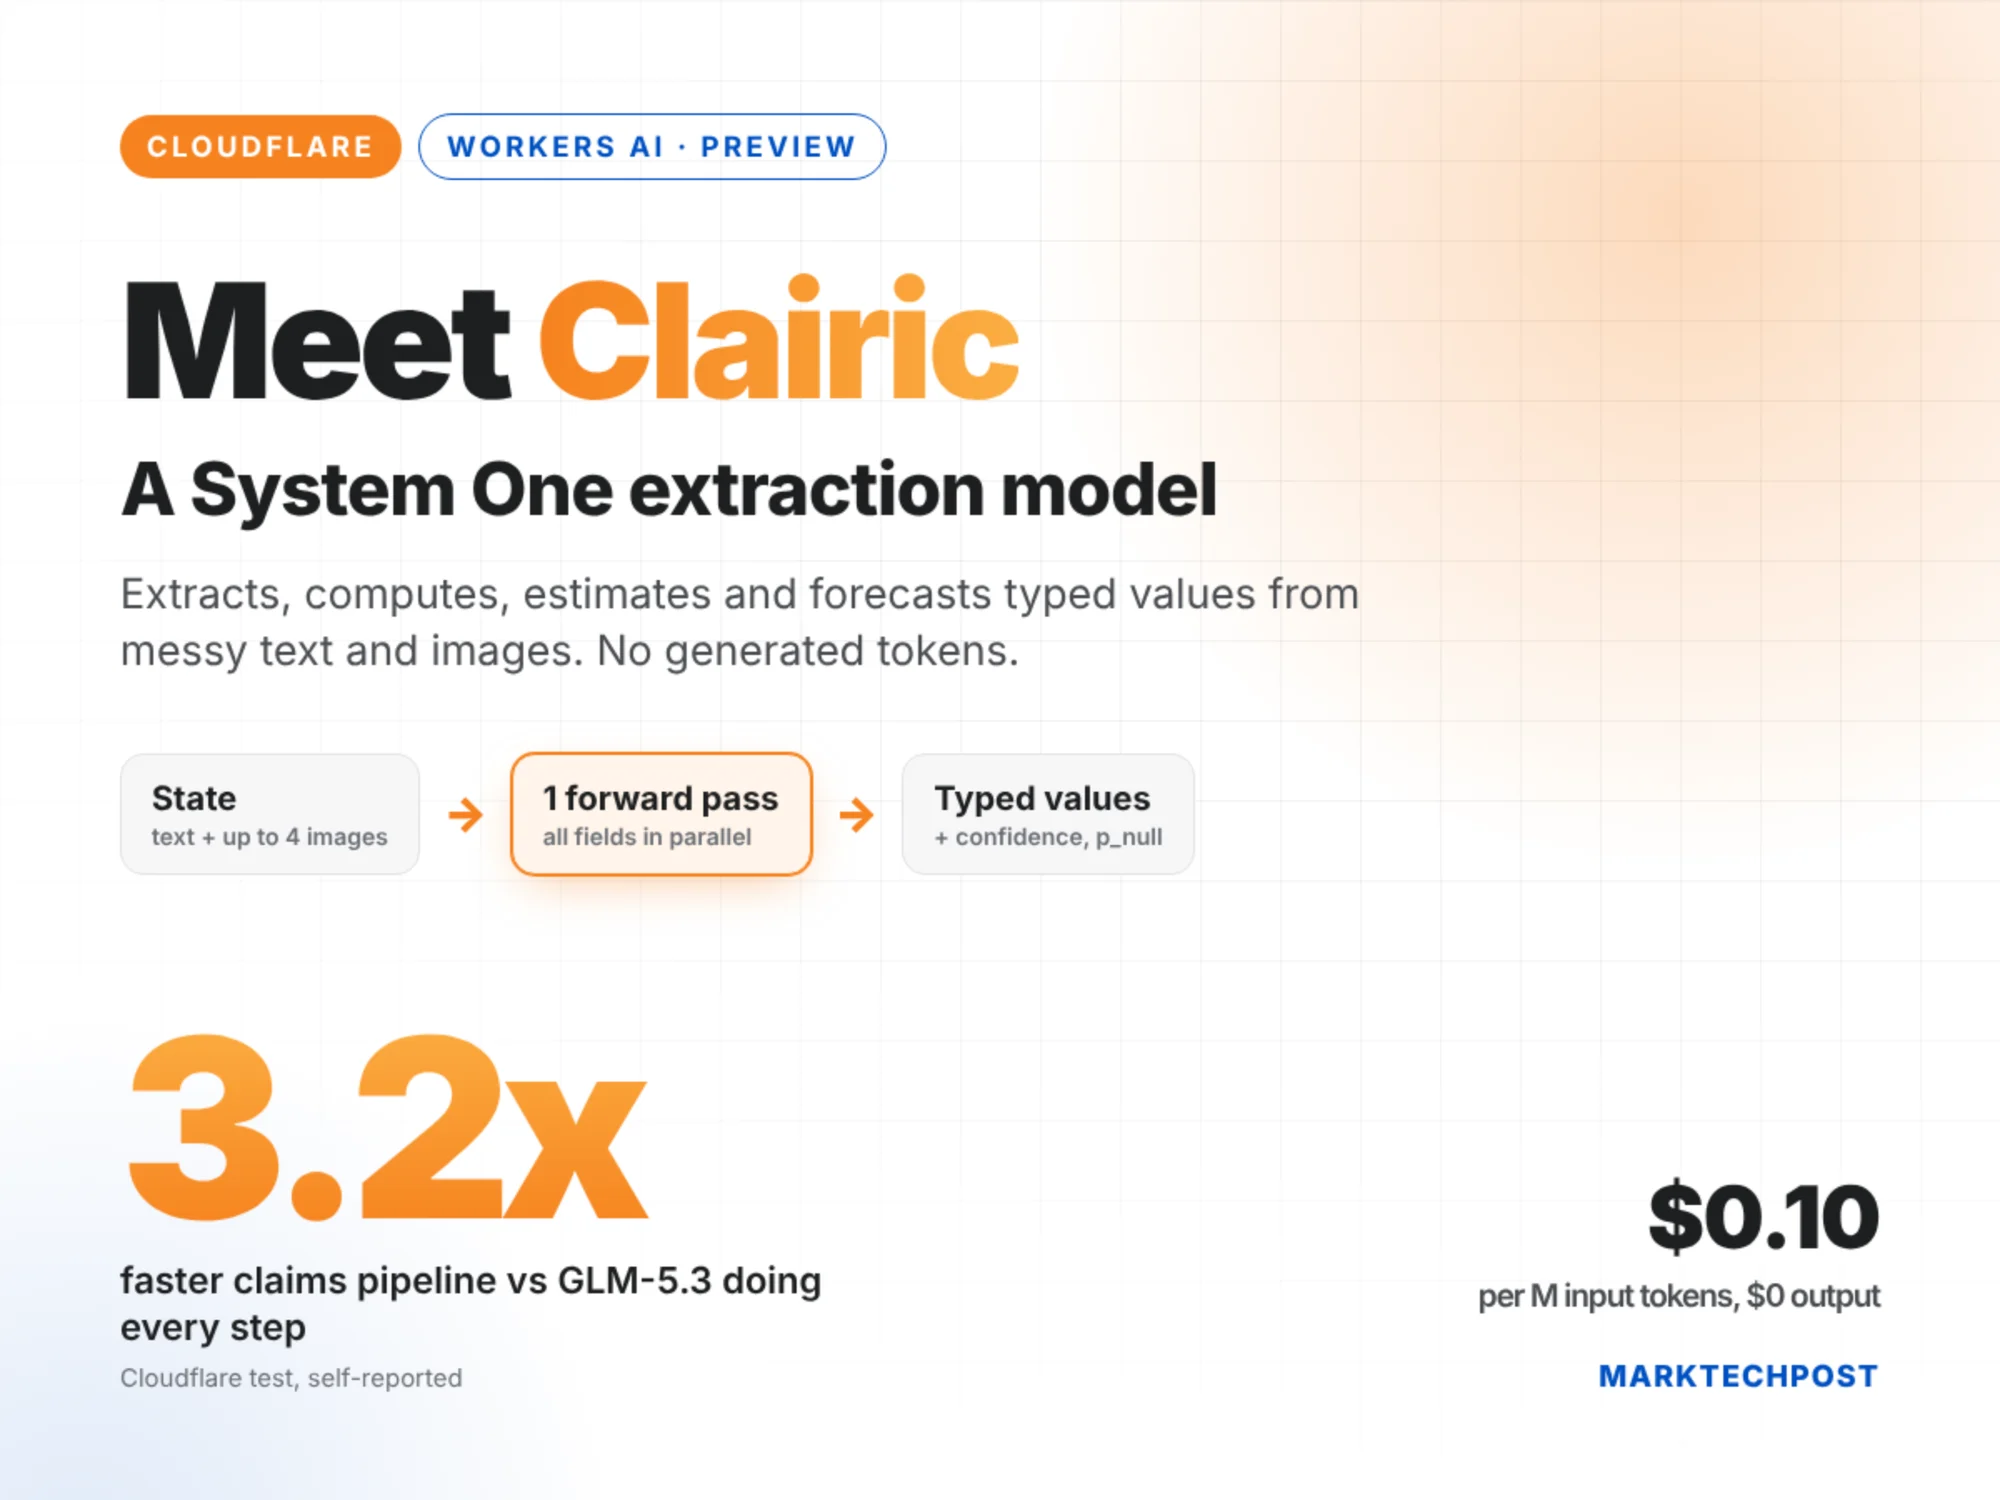
A Cloudflare bemutatta a Clairic nevű System One kinyerő modellt, amely a Workers AI felületén érhető el előzetes verzióban. Az eszköz nem generatív választ ad a lekérdezésekre, hanem a dokumentumokból vagy képekből strukturált, típusos adatokat (például számlaösszeget, dátumot vagy azonosítót) olvas ki JSON formátumban, egyetlen feldolgozási lépésben.
A modell 65 536 tokenes kontextusablakkal rendelkezik, és kérésenként legfeljebb 4 képet tud feldolgozni. Minden kiadott értékhez megbízhatósági pontszámot és hiányvalószínűséget csatol, a felismert szövegrészleteknél pedig a pontos karaktereltolást is megadja. A cég mérései szerint az adatkinyerési fázis mindössze 0,46 másodpercet vett igénybe a teszteken.
A szolgáltatás árazása 0,10 dollár 1 millió bemeneti tokenenként, míg a kimeneti tokenekért egyáltalán nem kell fizetni. A modell jelenleg a Cloudflare által hosztolt GPU-kon érhető el a `@cf/cloudflare/clairic` elérhetőségen keresztül, a nyílt súlyok kiadását későbbre ígéri a vállalat.
Az eredeti szöveg (MarkTechPost)
Cloudflare has released a preview of Clairic , a new System One extraction model on Workers AI. The Cloudflare Clairic extraction model reads text or images and returns typed values, not generated text. It targets a job developers usually give to LLMs: pulling totals, dates and IDs into JSON. Clairic answers every requested field in 1 forward pass, with no reasoning and no output tokens.
TL;DR
Size: Parameter count not disclosed. 65,536-token context window , up to 4 images per request.
Runs on: Cloudflare-hosted GPUs via Workers AI ( @cf/cloudflare/clairic ). No local option until weights ship.
Performance: Sub-second extraction in Cloudflare’s tests. No standard accuracy benchmark is published yet.
Best: Extraction step took 0.46 s vs 16.1 s for GLM-5.3 in Cloudflare’s claims pipeline.
Worst: 4 of 21 TSA next-day forecasts fell outside its 80% interval. Multi-step arithmetic is unreliable.
What is Clairic?
Clairic is a Cloudflare model that extracts, computes, estimates and forecasts typed values from unstructured inputs. It builds on the System One idea from TypeSafe’s Jev , named for Kahneman’s fast, intuitive thinking.
Jev and Cloudflare’s own Clef are decision models. They score options you list in advance. Clairic covers answers you cannot list, such as an invoice total, a date or a repair cost.
Cloudflare frames a 3-part stack. Extraction models turn raw input into typed values. Decision models turn values into decisions. LLMs turn decisions into words.
How does a Clairic request work?
A request has a state (text plus up to 4 images) and a map of named, typed fields . Each field can carry plain-language instructions. Supported types are text, number, date, time, datetime, duration, list, estimate and forecast, per the Workers AI changelog .
Every scalar answer includes p_null , the probability that the value is absent, plus a confidence score. Text answers return exact spans with character offsets. Estimates and forecasts return a median and an 80% interval, from p10 to p90. Forecasts cover up to 64 steps.
There is no field limit. Fields that do not fit beside the input in one 8,192-token pass split into parallel passes. Each pass sees the whole input. In the docs example, a 61-token invoice ran in 3 passes. It billed 655 input tokens, including 472 schema tokens. Wide schemas can cost more than the document itself.
What did Cloudflare’s tests show?
In a support-email example, Clairic added price and tax into $701.10. It also computed 11 days since delivery. Neither number appears in the email. A missing tracking number returned null instead of a plausible guess.
On a skewed receipt photo, it read all 7 present values and returned null for the absent discount. Its lowest confidence was 0.776, on the order number.
For forecasting, Cloudflare predicted daily TSA checkpoint counts for 21 days. Average error was 3.3%. 17 of 21 actual counts fell inside the 80% interval. 3 of the 4 misses fell on Columbus Day weekend.
The main test is a damaged-product claims pipeline. Clairic extracted facts, Clef chose refund or repair, and GLM-5.3 wrote the reply. Cloudflare compared this against GLM-5.3 handling all 3 steps.
The cascade finished in 19.3 s versus 61.7 s, about 3.2x faster. Extraction took 0.46 s against 16.1 s. The decision step took 0.22 s against 21.9 s. Cost per million claims fell 49%, from $11,740 to $6,032. The reply step still dominated, at 18.6 of the 19.3 s.
Both pipelines got the facts and decision right. Clairic’s repair estimate was identical across runs. GLM-5.3 returned $250, $250 and $220. Cloudflare says Gemma 4 and Qwen failed the all-LLM version.
How does Clairic compare with Clef, Jev and GLM-5.3?
Metrics Clairic Clef Jev GLM-5.3 Developer Cloudflare Cloudflare TypeSafe AI Z.ai Class System One extraction System One decision System One decision System Two LLM (reasoning) Output Typed values: spans, numbers, dates, durations, lists, estimates, forecast