Elon Musk reagált egy korábbi Google-alkalmazott elemzésére, amely szerint az adatközpontok kapacitása és az áramellátás jelentik a legfőbb szűk keresztmetszetet az AI-fejlesztésben. Musk hangsúlyozta, hogy az áramhiány emlegetése túlegyszerűsítés, mert a gigantikus számítási kapacitás rendkívül gyors online csatasorba állítása minden szempontból bonyolult. Ha kétszer annyi idő állna rendelkezésre, a folyamat lényegesen egyszerűbb lenne, de az időhiány szorít.
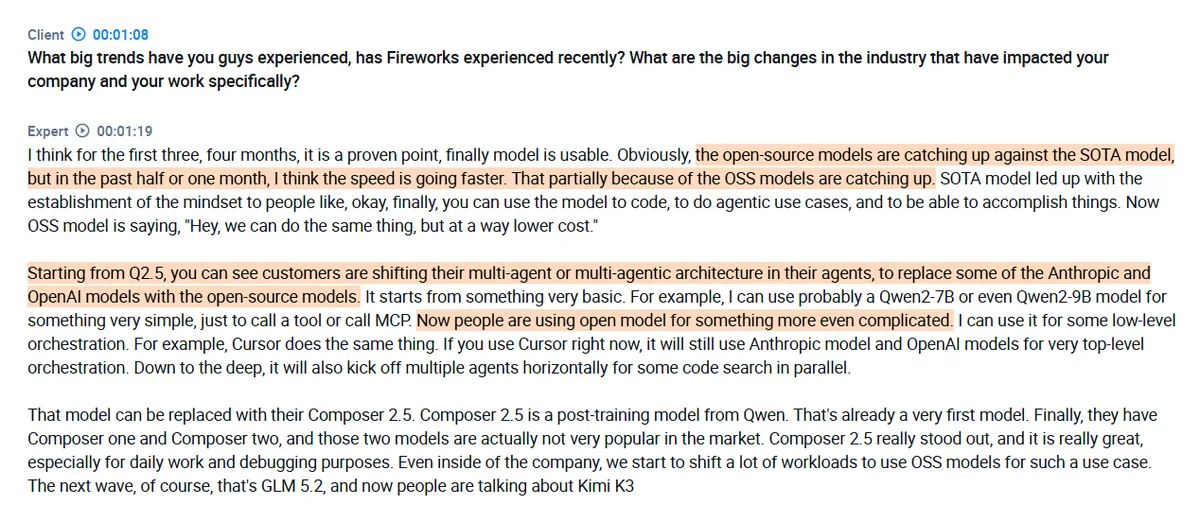
Az idézett szakértői meglátások alapján az AI-modellek használóinál a nyílt forráskódú megoldások egyre inkább felváltják a zárt modelleket az összetett rendszerekben. A növekvő felhasználói igényeket a meglévő amerikai kapacitások nehezen tudják kiszolgálni, a tengerentúli szerverek használata pedig a magas válaszidő miatt sokaknak nem elfogadható alternatíva.
A nagyobb felhőszolgáltatók drágák és hosszú kötelezettségvállalást követelnek meg, míg a kisebb, újabb szolgáltatók hardverei gyakran megbízhatósági problémákkal küzdenek. A szektorban a GPU-k fizikai elérhetőségénél jelenleg sokkal kritikusabb tényező a megfelelő adatközponti infrastruktúra kiépítése.
Az eredeti szöveg (Elon Musk (X))
“Lack of electricity” is an oversimplification. Everything is hard about bringing massive compute online at extremely high speed.
If there was twice as much time, this would be relatively easy, but there is not.
[IDÉZETT POSZT, amelyet Elon Musk megosztott. Eredeti szerzője: Rihard Jarc (@RihardJarc); megjelent: 2026-10-20T15:10:05+00:00; link: https://x.com/RihardJarc/status/2112562002958692392; média: 4 kép]
Former $GOOGL employee on why data center capacity and electricity are the real bottlenecks, not GPU production itself, and how unreliable some of the neoclouds are ($AMZN, $GOOGL, $MSFT, $NVDA):
1. According to the expert, open-source models are closing the gap with frontier models faster than expected, with customers increasingly replacing Anthropic and OpenAI models in multi-agent architectures with open-source alternatives starting from Q2 of this year. The shift started with simple tasks like tool calling and MCP, but has moved up the stack to low-level orchestration.
2. The expert identifies capacity as the biggest constraint at the moment, with certain companies' traffic growing 5x while GPU availability, particularly in the U.S. where latency requirements are tightest, simply cannot keep up. Sourcing capacity overseas in Asia or Australia is technically possible but adds latency that most customers will not accept.
3. Hyperscalers offer reliability but are expensive, require multi-year commitments of three or more years, and have limited availability of the latest hardware, with customers already chasing B300s. AI-native companies tend to gravitate toward neoclouds due to hyperscaler pricing and contract rigidity, but neoclouds come with their own reliability issues, with GPUs dropping off unexpectedly and requiring engineering resources to manage fleet stability around the clock.
4. The third tier consists of smaller independent operators who have invested in GPU racks, seeing the opportunity to lease out capacity and recoup costs within a year or two, with the remainder being pure profit. The expert describes these as essentially unusable in practice, with operators who do nothing more than find land, install racks, connect electricity, and set up cooling, with no real cloud management, maintenance, or operational expertise behind them.
5. The expert expects overall GPU availability to increase meaningfully over the next year or two, with $NVDA continuing to ramp production. The real bottleneck is not GPUs themselves but data center capacity and electricity in the U.S. On the supply side, the expert also sees players $SPCX beginning to lease out spare capacity to the market, with more likely to follow.
6. The expert notes that U.S.-based neoclouds typically require 20-30% prepayment upfront, with the remainder paid monthly or quarterly over the contract term, and rebates negotiated at the end for any reliability incidents like traffic loss. APAC-based providers operate differently, with no prepayment required at all.
found on @AlphaSenseInc